Dev log: teaching Hypha to see
We're building a photo check into Hypha that can flag contamination and tell when a flush is ready. Here's where it stands: 90,000 public photos, two human labelers, one frozen vision model, honest numbers, and what has to happen before it ships.
DerickUpdated 10 min read

Every grower knows the moment. You open the tent, look at a block you've babied for three weeks, and something looks off. Is that a bruise or the start of a blotch? Is that fuzz mycelium or mold? Is this cluster ready, or will it be better tomorrow?
Hypha already keeps a photo journal for every grow, and a lot of you are great about using it. Right now those photos are a record of what happened. What I've been building for the last couple of weeks is a way for them to help while it's happening: you add a photo, and Hypha takes a look too.
Hypha's photo check is still in development, so read this post as a development log, not a launch post. Hypha already runs the photo check in the background on new journal photos, but growers don't see its results yet. Below I'll be specific about what has to get better before they do.

What does Hypha's photo check look for?
Hypha's photo check answers three questions about every photo:
- Is this a grow photo at all? A gate, so the rest of the model never has to form an opinion about your cat or a screenshot of a receipt.
- Does anything look contaminated? Clean or contaminated, as a probability.
- What stage is the fruit at? Pins, young, ready to harvest, or past peak.
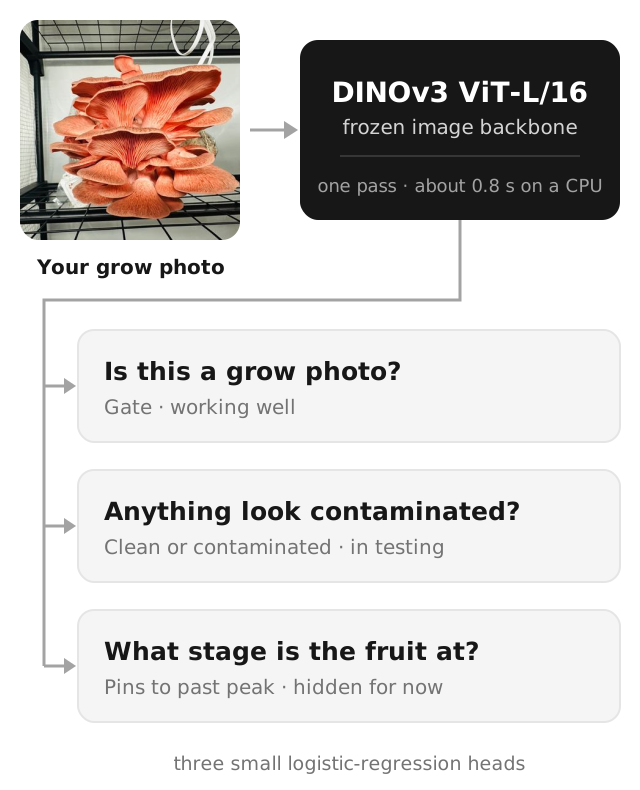
Under the hood, the photo check is one large pretrained vision model plus three tiny classifiers. The vision model turns each photo into a long list of numbers (an embedding), and the classifiers read those numbers. I'll get to why it's shaped like that in a minute.
Is Hypha's photo check trained on growers' photos?
No. The first version of Hypha's photo check doesn't train on the photos growers upload to Hypha, even though they're the obvious training set. Our privacy policy lets us use grower data, photos included, to improve Hypha's models, and you can email us at any time to leave yours out. That's automated use only: nobody on our team looks through your private photos to label them unless you've agreed to it. Running a model on your photo to give you an answer is one thing. Using your grow to teach it is another, and that's why you can always say no.
So I started where everyone starts: public datasets. I catalogued 150 of them (from Kaggle, Roboflow, Zenodo, Mendeley, Dataverse and GitHub), checked every license, and pulled in the ones we could use. That came to about 102,000 photos. After removing duplicates (the same oyster photos turn up in a lot of datasets) there were 89,809 left. Most are oysters and shiitake, with button mushrooms, king oysters, enoki, beech, reishi and agar plates mixed in.
Public data has a catch, though: everyone labels differently. One dataset's "contaminated" is another dataset's "bad photo." So we labelled our own.

Who labelled the photos, and did we agree?
Kaylee and I labelled the photos by hand, over a lot of evenings, on some simple review pages we built: 11,195 decisions across 5,090 photos. We agreed on obvious contamination, often split on fruiting stage, and couldn't agree on colonization at all. The pages were blind. They never showed an AI's guess, because it's far too easy to click "agree" on a suggestion late at night. A label that's really just a model agreeing with itself teaches the next model nothing.
Then Kaylee and I checked each other. Each of us re-labelled a blind sample of photos the other had already done, without knowing which ones they were or what the other person had said. It was humbling:
- Obvious contamination held up. When one of us called a photo clean or contaminated, the other gave the opposite answer on only about 1 in 12 photos. Most of our disagreements lived in the grey zone of "looks off" and "can't tell."
- Fruiting stage was fuzzy. We were within one step of each other 97% of the time, but where I said "young," Kaylee often said "ready to harvest."
- Colonization was a coin flip. Our agreement on how colonized a bag looked from a single photo was statistically no better than chance (Cohen's kappa of 0.03). Kaylee consistently saw less colonization than I did.

The colonization result changed the roadmap. I wanted a "should I break and shake this?" feature. But if two people who spend a lot of time staring at grain can't agree from one photo, a model trained on our labels won't do any better. It'll just be confidently arbitrary. Colonization is going to need a better signal than a single photo, and that's a problem for a future post.
How did I pick the model without fooling myself?
I scored every candidate vision model on photo sources it had never seen, so none could win by memorizing one dataset's quirks, and the winner was a frozen DINOv3 model. Here's the trap with public datasets. Each one comes from a single farm or lab, with one camera, one lighting setup and one kind of tub. A model can score brilliantly by learning "photos from this dataset are the contaminated ones" instead of learning what mold looks like. It looks great in testing and falls apart on your shelf. Researchers call this shortcut learning.
So every candidate is scored by leaving one source out: train on everything else, test on a dataset it has never seen, and repeat for each source. Holding out whole sources is how domain generalization research tests models on data unlike their training set. A separate evaluation set of held-out sources (12,376 photos) stays locked away. It's never used to make a choice, only to report numbers at the end.
With leave-one-source-out scoring in place, I let the GPU grind. I tried seven backbones (DINOv2 in three sizes, two SigLIP 2 models, NVIDIA's C-RADIO and Meta's DINOv3) across crops, pooling and regularization settings, plus a few rounds of full fine-tuning. That's roughly 600 trials per question, all on a single desktop GPU. Fine-tuning didn't beat the simpler approach.
The current pick is boring in the best way: DINOv3 ViT-L/16, frozen, with a plain logistic-regression head for each question. It isn't the top scorer on every task. C-RADIO edged it on contamination, but the gap was within the noise and C-RADIO costs about six times the compute. One forward pass serves all three questions.
The photo check runs on ordinary CPUs inside our own infrastructure, at about 0.8 seconds per photo in our benchmarks, and no third-party AI service sees the image. A frozen backbone has one more advantage while we're still developing: improving a head doesn't mean re-running the big model, so we can iterate quickly.
How accurate is the photo check today?
The photo check isn't accurate enough to ship yet: the gate mostly works, contamination detection is promising, and stage isn't good enough to show. These are the numbers from the current development build, measured on photos and sources the model didn't train on.
- The gate is in good shape, with one blind spot. The gate recognizes 99% of grow photos and rejects over 99% of the things that aren't. The exception is harvested mushrooms: picked mushrooms sitting on a tray or a table get through most of the time, because they look a lot like mushrooms on a block. (To be fair, they are mushrooms.)
- Contamination is promising, not ready. Tested on datasets left out of training, the contamination model scores an AUC of about 0.84. Going by Hanley and McNeil's 1982 paper, that score means a random contaminated photo gets ranked more suspicious than a random clean one about 84% of the time. The score swings a lot by source, from 0.68 on the hardest to 0.95 on the easiest. On a fresh batch of our own labels, the model caught 5 of 13 contaminated photos. Thirteen is a small sample, but five isn't a number I'd put in front of a grower.
- Stage isn't good enough to show yet. Overall accuracy is 57%. It's decent at "ready to harvest" (81%) and close to useless at pins (5%). Worse, a model that answered "ready to harvest" every single time would beat it on our main metric. So stage stays hidden while we work on it.

Catching 5 of 13 contaminated photos and getting 57% of stages right is why the photo check isn't telling growers anything yet. I'd rather ship nothing than a confident, wrong opinion about your grow. Until the photo check ships, our contamination ID guide shows how to spot contamination by eye.
How will the photo check help growers?
Hypha's photo check is meant to be a second pair of eyes that never gets tired, not a robot that grades your mushrooms.
- Catching trouble early. Contamination spreads, and the earlier you spot it, the more of your room you save. What we're aiming for is a gentle "this one looks off, take a closer look" on the photo you just added. Not a verdict.
- Harvest timing. Oysters go from perfect to past peak fast (when a mushroom is ready). A nudge when a block looks ready, alongside your schedule, means less guessing.
- Photos plus sensors is the part I'm most excited about. Long stems with tiny caps is the classic sign of too much CO2 (CO2 and fresh air guide), and cracked, dry caps usually mean low humidity. But a photo alone can't tell high CO2 from low light, or low humidity from a fan blowing straight onto the caps. If you run a Hypha Aeris sensor (closed beta, not for sale yet), Hypha also has your zone's CO2 and humidity history. A model that spots the symptom, plus the sensor log that explains it, can tell you why and what to change. We've started labelling those symptoms, but there's no model for them yet. The sensor can sometimes see what the camera can't: as the caps open, the air fills with spores, and our Aeris caught that rise while the photos looked unchanged.

What's next for the photo check?
Five steps, roughly in order:
- Shadow mode in production, now running. Hypha scores new journal photos quietly in the background, and growers don't see a result. We check the model's thresholds against photos from our own grows and from growers who explicitly opt in.
- A smarter gate that knows a harvest photo when it sees one.
- A golden set: a carefully labelled, blind test set the model has never touched. Nothing in the app will ever say "likely contamination" until the model passes it.
- A better way to measure stage, so "always say ready" can't win.
- Labels from growers, if they want to help. Down the road, we'd like growers who opt in to be able to tag their own photos in the app ("first pins," "something's wrong here") and help teach it. Tagging will always be optional.
Grower labelling is how the photo check becomes a community project. A photo you tag teaches the model something, and what it learns from your grow helps the next grower catch the same problem on theirs. Sharing your data is how growers give back to each other, and we're grateful to everyone who contributes. This whole project already rests on that kind of generosity: the photos it learned from were published openly by growers and researchers who wanted to help. Thank you.
I'll keep posting updates on the photo check here as it moves along. If you have questions about how any of this works, or opinions about what it should flag first, write to us at team@demetermycolabs.com. I read all of it.
— Derick
Built with DINOv3. The image backbone is Meta's DINOv3 (ViT-L/16), used under the DINOv3 License. Thanks also to the many researchers and growers who published their mushroom photo datasets openly. None of this works without them.